Pharma's chain of custody model is migrating into food and consumer goods — and becoming a cross-industry differentiator.
Waiting for perfect data before deploying AI is a trap — and why 60-70% accuracy is often good enough to start.
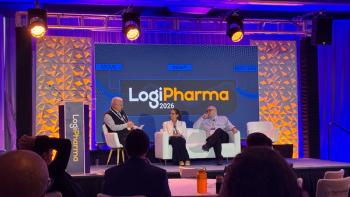
Pharmaceutical Executive spoke with Mark Talens, CCO of PAXAFE at LogiPharma 2026 in Boston. During the conversation., the executive discussed a variety of issues and updates on modern supply chains and the most important issues impacting them in today’s world.
Talens discussed how many companies haven’t properly organized their data in order to work best with modern technology. He also discussed broader organizational gaps in supply chains, citing many companies’ lack of cross-functional generalists as a significant issue.
Talens also detailed another major issue: the balancing of business-minded SOPs with real-world operations. While many companies think ahead to build in redundancies, they aren’t as prepared as they should be for certain real-world situations.
Pharmaceutical Exeutive: What does best-in-class supply chain data infrastructure look like today?
Mark Talens: I actually sit on two trains of thought on this one, so let me start with the more controversial position.
Stop obsessing over the quality of your data. Let me explain what I mean by that.
Your data will never be 100% clean. I have spent millions of dollars at my former companies on master data management — aggregating data, building standards, creating a single source of truth. Those projects took six, nine, twelve months. What if you simply loaded the data as-is, created context around it, and ran an agent over it? In many of the problems we need to solve, data that is 60 or 70 percent accurate is often good enough. The question you should ask yourself is this: would 100% accuracy in my data materially change the decision I am making?
I want to be clear — this is not true everywhere, and I know some people will immediately reach for the edge cases where it is not true. My point is: start with the 80% of use cases where it will work. Accept that it will not work everywhere. Put controls in place to catch the cases where it does not, and then begin targeted optimization from there. You are flipping the conventional approach on its head.
Now for the second point, because I do agree that data understanding and data completeness matter. If you start throwing everything into large datasets and running agents and LLMs over poorly structured data, you begin to lose track of what you are actually solving. I am not saying data quality is irrelevant. But I am increasingly frustrated when I go to conferences and hear companies say they need to spend two more years getting their data right before they can start. If that is your attitude, you will never be ready.
Start with a use case where you can solve a real problem with your data as it exists today. And here is a useful perspective check: if you are a $20 billion publicly traded company telling me your data is absolutely terrible, it cannot be that bad — because you are running a profitable business. You are doing something with it, even if it is inefficient. Do not get paralyzed by perfectionism and miss the opportunity to learn how to connect and contextualize your data through real use cases.
Don't treat data quality as a problem that must be solved sequentially before anything else can begin. Treat it as a parallel problem — one that often improves as a byproduct of deploying use cases and learning cycles. We have demonstrated that repeatedly. It takes effort, but the data works itself out through the process, not before it.